Self-Hosted LLMs vs Cloud APIs: A Practical Guide for SMEs
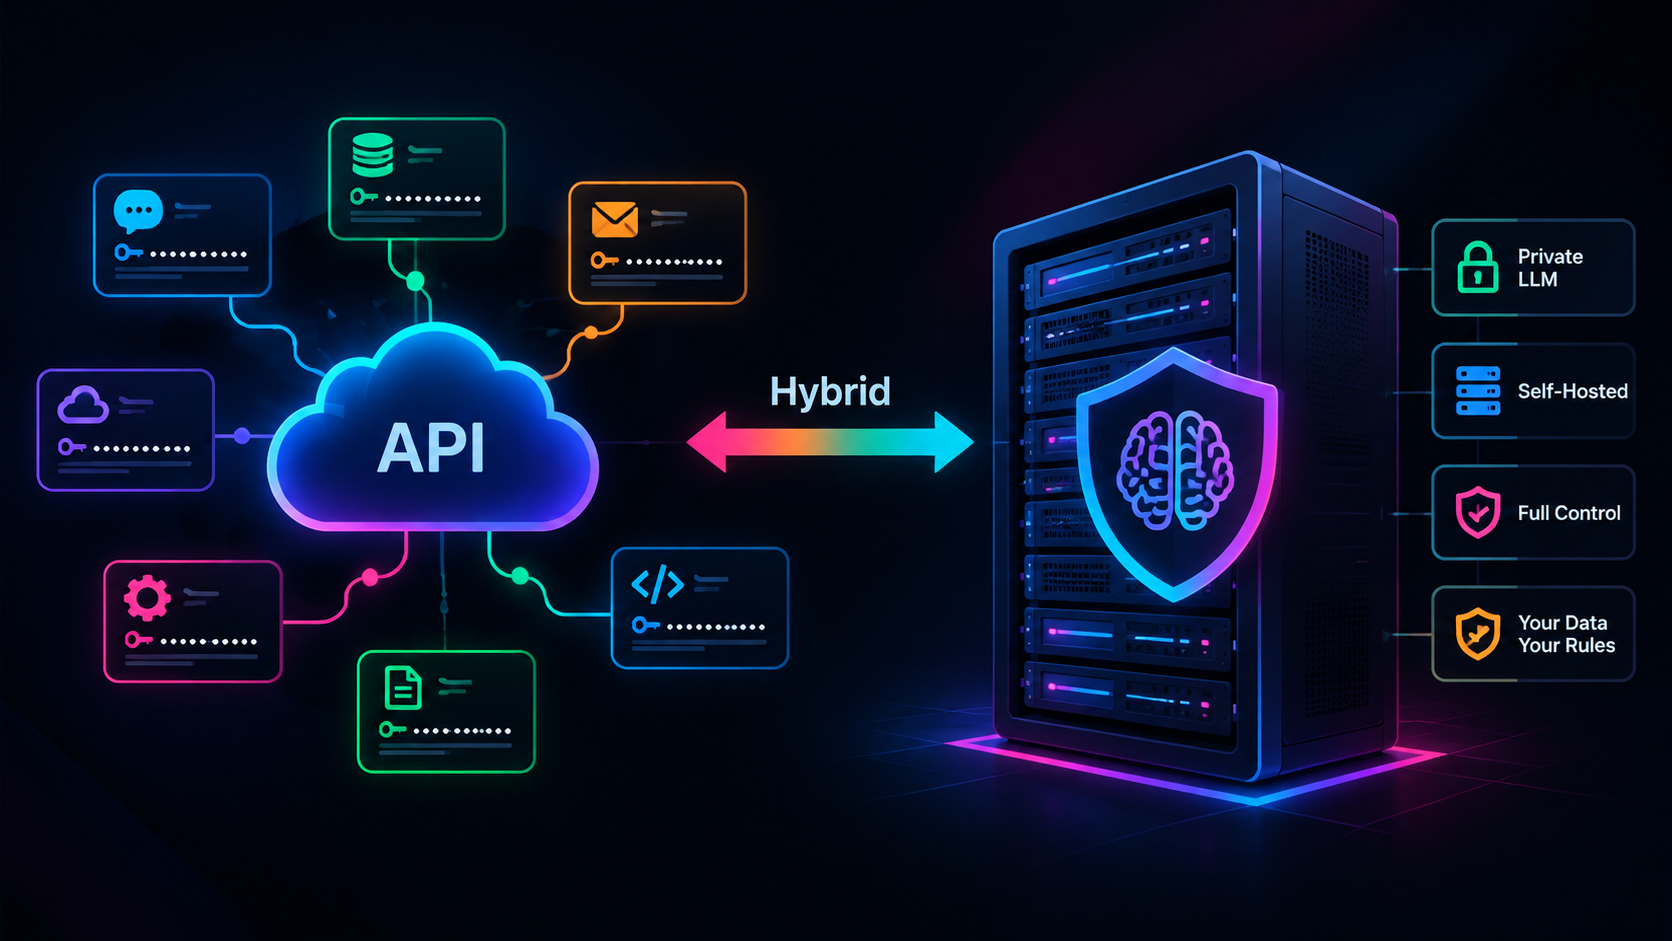
Cloud AI APIs are fast to start. Self-hosted / local LLMs keep sensitive data closer to home. Most businesses don’t need a religious debate — they need a routing policy.
Here’s how we decide for SME and mid-market clients.
The real decision is risk + volume + latency
Ask three questions:
- Risk — What happens if this prompt content leaks or is retained by a vendor?
- Volume — Will we send thousands of documents/day, or a few dozen?
- Latency / control — Do we need offline capability, custom models, or predictable unit economics?
If risk is high, prefer private inference. If volume is low and content is non-sensitive, cloud APIs are usually fine.
Where cloud APIs win
- Rapid prototyping and demos
- Marketing copy, SEO drafts, brainstorming
- Low-sensitivity internal helpers
- Access to frontier models without GPU ops
Tradeoffs: data handling policies, rate limits, and cost spikes at scale.
A hybrid architecture that works
A pattern we ship often:
- Cloud LLM for non-sensitive drafting and ideation
- Self-hosted LLM for PII-heavy classification, extraction, and RAG over private docs
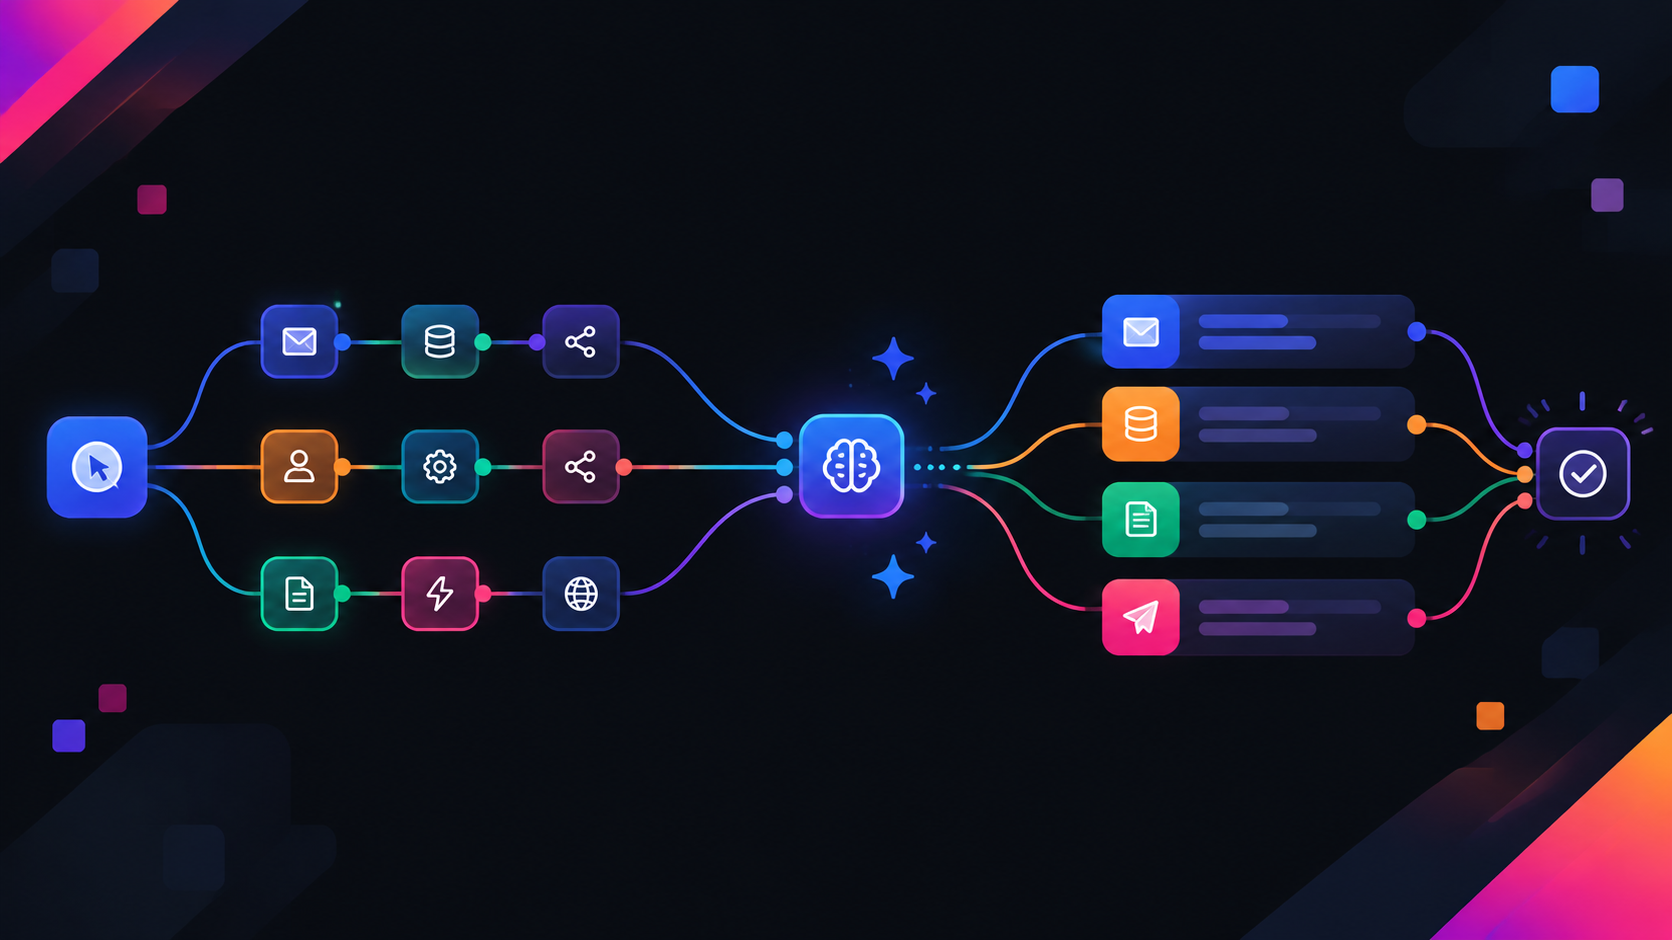
- Workflow layer (n8n/Make) for triggers, retries, logging
- Human approval for outbound customer messages and irreversible actions
This is usually better than forcing one model into every job.
RAG changes the equation
Most business “chatbots” fail because they lack grounded retrieval. A useful private assistant needs:
- Document ingestion + chunking
- Access control by role/team
- Citation / source links
- Escalation when confidence is low
The model is only one piece. Retrieval quality and permissions matter more than brand-name benchmarks.
Cost reality check
Cloud looks cheaper until:
- You embed and re-embed large corpora repeatedly
- Agents make multi-step tool calls
- You run always-on support deflection
Self-hosted looks expensive untStart with cloud if the data is safe to send. Move sensitive workloads to self-hosted inference as soon as you have a production use case and an owner for uptime.
If you want a production-ready private AI stack — agents, RAG, and workflow automation — teams like CodeMyPixel build and operate these systems for US and EU clients.
Explore:
*For founders and IT leads choosing between private and cloud AI inference.*il:
- GPU is utilized most of the day
- You avoid per-token surprises
- Compliance reduces vendor risk reviews
Run a 30-day cost model with real ticket/doc volume, not demo usage.
Bottom line
Where self-hosted / local LLMs win
- Customer support transcripts and tickets
- Contracts, invoices, HR, and medical-adjacent workflows
- On-prem or VPC requirements
- Stable high-volume inference once hardware is sized
Tradeoffs: model selection, GPU capacity, evals, and MLOps ownership.